a deep dive into codex

Codex looks like a chat interface, but the model is only one component. The useful system is a loop around the model: collect context, ask the model what to do, execute tools, return their results, enforce permissions, persist the history, and repeat until the task is complete.

That distinction explains why an agent can work across a repository while a plain language model can only propose text. Codex can observe the real result of a command or edit and use that feedback in its next decision.

This article develops a source-level mental model of the open-source Codex runtime. Names and file paths reflect a snapshot of the implementation and may move; the architectural boundaries are the durable part. For the current public protocol and behavior, use the Codex app-server documentation as the source of truth.

1. The big picture

The runtime can be understood as five layers:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
┌──────────────────────────────────────────────────────────────┐
│ Frontends │
│ TUI · exec · CLI · IDE extension · VS Code · Codex Web │
└──────────────────────────────┬───────────────────────────────┘
│ app-server protocol
│ thread/* · turn/* · item/*
┌──────────────────────────────▼───────────────────────────────┐
│ App server │
│ Translates client requests and streams events │
│ In-process for some clients; stdio/WebSocket for others │
└──────────────────────────────┬───────────────────────────────┘
│
┌──────────────────────────────▼───────────────────────────────┐
│ Core engine │
│ Session/thread → task → model/tool loop │
│ │
│ model client ────────────────► Responses API │
│ tool orchestrator ───────────► shell · apply_patch · MCP │
│ rollout recorder ────────────► persistent history │
└──────────────────┬─────────────────────────┬─────────────────┘
│ │
┌──────────▼──────────┐ ┌──────────▼──────────┐
│ Approval policy │ │ OS sandbox │
│ user / rules / │ │ filesystem, process │
│ automated reviewer │ │ and network limits │
└─────────────────────┘ └─────────────────────┘

The frontends do not each implement their own coding agent. They present different views over the same underlying engine. The app server provides the integration boundary: authentication, conversation history, approvals, streamed events, and thread/turn operations. This separation lets the TUI and an IDE extension behave differently without duplicating the agent loop.

The core engine owns the work. It prepares model input, receives a streamed response, dispatches requested tools, feeds observations back to the model, and records what happened. Approval routing decides whether an action may proceed; the sandbox limits what a permitted command can actually touch.

This is the most important high-level split:

  • the model proposes actions;
  • the harness coordinates the loop;
  • the tools interact with the world;
  • the policy layer decides when human authorization is required;
  • the sandbox enforces the technical boundary;
  • the rollout makes the work resumable and inspectable.

The same pattern appears in OpenAI’s managed agent architecture: a harness runs the model/tool loop, while a separate environment provides files and compute. The local Codex runtime places that idea on the developer’s machine.

2. The core mental model: queues, sessions, tasks, and turns

At the source level, Codex behaves like a headless asynchronous service. A user interface communicates with it through two logical streams:

  • Submission queue (SQ), UI → Codex. User input and control messages enter the engine: start work, interrupt, answer a question, or resolve an approval.
  • Event queue (EQ), Codex → UI. Progress returns to the client: text deltas, item updates, approval requests, errors, and completion events.

This is why the engine is reusable. The transport can be an in-process channel, standard input/output, or a socket; the core still sees requests arriving in one direction and events leaving in the other. The current app-server protocol exposes this model as JSON-RPC requests plus thread/*, turn/*, and item/* notifications.

The state hierarchy in the photographed source notes is:

Concept Meaning Typical source area
Session Configuration and state for one conversation; normally one active unit of work at a time core/src/session/
Task Work initiated by one user request; it can require several model/tool iterations core/src/tasks/
Turn One pass through prompt construction, model streaming, and tool-result handling core/src/session/turn.rs

There is a terminology trap here. In the public app-server API, a thread is the persistent conversation and a turn is the user-visible cycle started by turn/start. Internal names can be finer-grained and can change over time. When integrating with Codex, follow the public protocol; when reading the source, first identify what that version means by session, task, and turn.

3. The agent loop

The turn loop is the heart of Codex. Conceptually, each iteration does five things.

3.1 Build the prompt

Codex assembles the material the model needs: system and developer instructions, repository guidance such as AGENTS.md, conversation history, the current request, available tool definitions, relevant environment state, and any tool results from the previous iteration.

The prompt is therefore not just the latest chat message. It is a structured snapshot of the task and the world around it.

3.2 Stream the model response

The client sends the prompt to the Responses API and consumes a stream of response events. Streaming lets the UI show commentary as it arrives and lets the runtime recognize tool calls without waiting for one monolithic response.

Connection retries, backoff, and transport fallback belong at this boundary. They are reliability details around the loop, not agent reasoning. A completed response can also provide an identifier that helps preserve continuity or resume work.

3.3 Dispatch tool calls

When the model asks to run a command, edit a file, search the web, call an MCP server, or use another tool, the orchestrator resolves the tool by name and invokes its implementation. Independent calls may run in parallel; dependent calls must wait for the observations they require.

Before execution, sensitive actions pass through approval policy and sandbox preparation. The model does not bypass those layers merely by emitting a tool call.

3.4 Feed observations back

Tool output becomes new model input. A compiler error, failing test, command exit code, file diff, or search result is not a side channel: it is the evidence that lets the next iteration adapt.

1
2
3
4
5
user request
↓
build context → call model → tool request → execute tool
↑ ↓
└────────────── tool result ───────────┘

The loop continues while the model requests more work. When it produces a final response without another tool request, the task can finish.

3.5 Persist incrementally

Messages, tool calls, results, and state changes are appended to the rollout as work happens. Incremental persistence matters: a long task should remain inspectable and recoverable even if the process or connection fails before the final answer.

This loop is why verification is so valuable. Tests, builds, linters, and diffs turn assumptions into observations. OpenAI’s write-up on long-horizon Codex tasks describes the same operating rhythm: plan, edit, run tools, observe, repair, and repeat.

4. Tools: one interface, many capabilities

Codex keeps a registry of tools and dispatches calls by name. The implementations differ, but the model sees a common pattern: a name, an input schema, and a result.

Shell execution

The shell tool runs commands and returns their output and exit status. It is the bridge from language reasoning to compilers, tests, Git, package managers, and project-specific scripts. Because shell access is powerful, it is also the path most tightly connected to approvals and sandboxing.

apply_patch

File editing uses a patch-oriented tool rather than asking the model to rewrite whole files blindly. The format describes add, update, and delete operations, and a streaming parser can validate and apply the patch as it arrives.

Patch-based editing has three useful properties:

  1. The intended change is explicit.
  2. The resulting diff is easy for a human to inspect.
  3. Unrelated content is less likely to be overwritten.

MCP tools

External Model Context Protocol tools are adapted into the same internal tool shape, so the model can use a remote service much like a built-in capability. Codex acts as an MCP client when it connects to external tool servers over transports such as stdio or HTTP and exposes their catalogs to the model.

Older Codex versions could also expose Codex itself as an MCP server, allowing another agent or IDE to drive a Codex conversation. That direction is visible in the source snapshot behind this article, but it is no longer the recommended integration path. Current documentation directs new deep integrations to the Codex app server and automation or CI use cases to the Codex SDK; the legacy Codex MCP server is deprecated.

The architectural lesson survives that migration: protocol adapters should terminate at a stable tool or application boundary rather than leaking transport details into the core loop.

5. Sandboxing and approvals: two different gates

Codex’s security model separates a policy decision from technical enforcement.

Approval routing asks “may this action proceed?”

A command is compared with the active approval policy and execution rules. Depending on the result, it may run automatically, prompt the user, or be reviewed by another configured mechanism. Equivalent approved command shapes can be remembered for an appropriate scope so the user is not repeatedly asked the same question.

The sandbox asks “what can this process actually do?”

Even after approval routing, the command runs under an OS-enforced boundary. Current Codex documentation describes local execution as a combination of an approval policy and a sandbox that normally limits writes to the workspace and keeps network access off by default.

The implementation is platform-specific. In the source snapshot:

OS Main enforcement mechanism
macOS Seatbelt sandbox profiles
Linux Landlock, seccomp, no_new_privs, and bubblewrap where available
Windows Restricted tokens and deny ACLs

The runtime also applies process hardening, such as constraining tracing or core dumps and scrubbing dangerous loader-related environment variables before launching a child process. Some deployments place the actual spawn operation in a separate executor with a virtual filesystem policy.

Keeping these layers separate is deliberate:

1
2
3
4
5
6
7
8
9
model requests action
↓
policy and approval routing
↓
per-OS sandbox transformation
↓
process execution
↓
captured output returned to the loop

Approval is not a substitute for containment, and containment is not a substitute for informed approval. The former expresses user intent; the latter limits blast radius. See Agent approvals & security for current behavior and configuration.

6. Persistence: why a session can resume

A Codex session is a persistent conversation identified by a stable thread ID. Each user-visible unit of work has its own turn ID. The local rollout is an append-oriented JSONL transcript containing information such as:

  • user and agent messages;
  • tool calls and results;
  • thread and turn metadata;
  • token usage and compaction events;
  • environment and execution context needed to understand the work.

Depending on the Codex version, active rollout files have appeared under date-partitioned paths inside ~/.codex/sessions/ or related thread storage. Treat that layout as generated implementation state, not as a stable API.

The rollout enables several features:

  • resume reconstructs enough context to continue the conversation;
  • fork creates a new line of work from an earlier point;
  • diagnostics can explain which messages and tools led to an outcome;
  • compaction summarizes older material when the context window fills;
  • memory extraction can distill reusable context from eligible completed work.

These files can contain prompts, source code, local paths, commands, and tool output. They should be treated as sensitive. Archiving retains the transcript; deletion removes persisted thread data. The app server exposes explicit operations for both lifecycle choices.

7. Memory is derived context, not authority

Conversation persistence and memory solve different problems. A rollout preserves one thread in detail. Memory extracts a smaller amount of potentially useful context so it can help in future threads.

The pipeline is roughly:

1
2
3
4
5
6
7
session rollout JSONL
↓
phase 1: per-thread extraction
↓
phase 2: global selection and consolidation
↓
reusable local memory files

The first phase can produce compact facts about tasks, outcomes, preferences, reusable knowledge, failures, and references, plus a readable summary of the thread and evidence linking the memory back to its source. The second phase selects useful, current entries and consolidates them into the global memory store.

In the implementation snapshot, an extraction record separates raw_memory, a readable rollout_summary, and a short rollout_slug. Version fields such as source_updated_at and generated_at identify the rollout used to create it. Bookkeeping fields such as usage_count, last_usage, selected_for_phase2, and a phase-two source watermark help the consolidator measure reuse and avoid treating a stale selection as current. These are useful for understanding the pipeline, but they are internal storage details rather than a stable API.

Local Codex memories live under ~/.codex/memories/. The generated state can include summaries, durable entries, recent inputs, and supporting evidence. Codex waits for eligible threads to become idle before processing them, and it can skip extraction because of age, external-context policy, or available rate limit.

Two controls are intentionally independent:

  • memories.generate_memories decides whether new chats may contribute to future memory;
  • memories.use_memories decides whether existing memories may be injected into future sessions.

The /memories command changes these choices for the current chat; config.toml supplies global defaults. Disabling either control does not delete stored memories and does not stop ordinary session persistence.

The most important rule is conceptual: memory is a recall layer, not an authoritative source. Requirements that must always be followed belong in AGENTS.md or checked-in project documentation. Memories can be stale, incomplete, or irrelevant to a new task. The current Codex memories documentation makes the same distinction.

8. A practical source-reading order

If you want to trace the implementation rather than reading the repository from top to bottom, this order keeps the concepts connected:

  1. codex-rs/docs/protocol_v1.md or the current protocol documentation — learn the vocabulary and event sequence first.
  2. core/src/session/turn.rs — find the main agent loop.
  3. core/src/client.rs — see how Codex talks to the model and consumes streaming responses.
  4. core/src/tools/orchestrator.rs and apply-patch/ — follow tool dispatch and file editing.
  5. sandboxing/ and execpolicy/ — trace policy, approval, and OS enforcement.
  6. AGENTS.md at the repository root — understand contributor-facing conventions before interpreting or changing the code.

Paths in a fast-moving repository will change. Search by concepts and types when a path no longer exists: thread, turn, rollout, orchestrator, approval, sandbox, and app server are better anchors than a frozen directory tree.

9. What the architecture gets right

Several design choices make Codex more than a code-generating chat:

The UI is decoupled from the engine

A TUI, IDE, desktop app, or custom integration can share the same lifecycle and safety semantics. New frontends do not need to reinvent the agent.

Feedback is part of reasoning

The loop treats command output and file changes as first-class observations. Codex can repair a failed build because the failure becomes context, not because the model somehow predicted every consequence in advance.

Safety is layered

Policy, human approval, sandbox transformation, and process execution are distinct components. Each can evolve without collapsing the whole security model into a single yes/no switch.

State is externalized

Repository files, rollouts, diffs, plans, and memory records give long-running work durable state. The model does not have to carry everything inside one transient response.

Integration boundaries are explicit

Tools normalize capabilities, the app server normalizes clients, and persistence normalizes continuation. These boundaries are what let the system grow without placing every responsibility inside the model prompt.

Conclusion

The cleanest way to understand Codex is not “an LLM that can run shell commands.” It is a stateful agent harness built around a model:

1
context → model → action → guarded execution → observation → persisted context

The model supplies judgment, but the surrounding runtime supplies continuity, evidence, permissions, and a real environment. The app server makes the engine usable from many clients; the tool layer makes external capabilities uniform; the approval and sandbox layers make execution governable; rollouts and memory let useful state survive beyond a single response.

Once this loop is visible, Codex’s behavior becomes much easier to reason about. A strong prompt helps, but reliable agentic work comes from the whole system: clear instructions, bounded tools, observable results, durable state, and verification at every meaningful step.
cmake

1
cmake .. -DTARGET_PLATFORM=macos_arm64 
1
2
3
4
5
6
7
8
9
10
11
12
13
set_source_files_properties(cuda/ntt/parameters.cuh PROPERTIES LANGUAGE CUDA)
set_target_properties(cryptography_cuda
PROPERTIES
CUDA_RUNTIME_LIBRARY Shared
# CUDA_STANDARD 14 # this one cannot be changed by CMake
# CUDA_SEPARABLE_COMPILATION ON # not needed for this example
)
# # # set_property(TARGET CUDA_COMP PROPERTY CUDA_ARCHITECTURES 86-real 86-virtual)

set_target_properties(cryptography_cuda PROPERTIES POSITION_INDEPENDENT_CODE ON)
set(CUDA_NVCC_EXECUTABLE "/usr/local/cuda/bin/nvcc")
# find_library(CUDA_LIBRARY cuda HINTS ${CMAKE_CUDA_IMPLICIT_LINK_DIRECTORIES})
# target_compile_features(cryptography_cuda PRIVATE cuda_std_14)
  • CUDA_SEPARABLE_COMPILATION
    1
    2
    find_package(CUDAToolkit REQUIRED)
    set(CUDA_SEPARABLE_COMPILATION ON)
    Separable compilation allows the compilation of individual CUDA source files (*.cu) into separate object files, which can be linked together later. This can result in faster incremental builds, as changes to one CUDA source file may only require recompilation of that specific file.

Nvidia cuda dev all in one

NVCC

nvcc predefines the following macros:

  • NVCC (1): Defined when compiling C/C++/CUDA source files.
  • CUDACC (1): Defined when compiling CUDA source files.

compile a single cuda file

1
nvcc -gencode arch=compute_70,code=sm_70 -g -G kernel.cu -o kernel

memory

data transfer

gdr

https://developer.nvidia.com/gdrcopy

pinned pageable memory

https://developer.nvidia.com/blog/how-optimize-data-transfers-cuda-cc/

nvlink command

1
nvidia-smi nvlink -h

To show active NVLINK Connections, you must specify GPU index via -i

1
nvidia-smi nvlink --status -i 0

example output

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
GPU 0: NVIDIA H100 PCIe (UUID: GPU-a1bf2ff6-a98d-edac-a422-0bd80fbd9724)
Link 0: 26.562 GB/s
Link 1: 26.562 GB/s
Link 2: 26.562 GB/s
Link 3: 26.562 GB/s
Link 4: <inactive>
Link 5: 26.562 GB/s
Link 6: 26.562 GB/s
Link 7: 26.562 GB/s
Link 8: 26.562 GB/s
Link 9: <inactive>
Link 10: <inactive>
Link 11: 26.562 GB/s
Link 12: 26.562 GB/s
Link 13: 26.562 GB/s
Link 14: 26.562 GB/s
Link 15: <inactive>
Link 16: <inactive>

Allows you to query to ensure each link associated with the GPU Index (specified by -i #) has specific capabilities related to P2P, System Memory, P2P Atomics, SLI.

1
nvidia-smi nvlink --capabilities -i 1

example output

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
Link 0, P2P is supported: true
Link 0, Access to system memory supported: true
Link 0, P2P atomics supported: true
Link 0, System memory atomics supported: false
Link 0, SLI is supported: false
Link 0, Link is supported: false
Link 1, P2P is supported: true
Link 1, Access to system memory supported: true
Link 1, P2P atomics supported: true
Link 1, System memory atomics supported: false
Link 1, SLI is supported: false
Link 1, Link is supported: false
Link 2, P2P is supported: true
Link 2, Access to system memory supported: true
Link 2, P2P atomics supported: true
Link 2, System memory atomics supported: false
Link 2, SLI is supported: false
Link 2, Link is supported: false
Link 3, P2P is supported: true
Link 3, Access to system memory supported: true
Link 3, P2P atomics supported: true
Link 3, System memory atomics supported: false
Link 3, SLI is supported: false
Link 3, Link is supported: false

nvidia-smi nvlink -g N -i N allows you to view the data being traversed on the different NVLink Link.

1
nvidia-smi nvlink -g 0 -i 0

benchmarking p2p mem_copy

code for testing p2p memCopy

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
// P2P Test by Greg Gutmann

#include "stdio.h"
#include "stdint.h"

int main()
{
// GPUs
int gpuid_0 = 0;
int gpuid_1 = 1;

// Memory Copy Size
uint32_t size = pow(2, 26); // 2^26 = 67MB

// Allocate Memory
uint32_t* dev_0;
cudaSetDevice(gpuid_0);
cudaMalloc((void**)&dev_0, size);

uint32_t* dev_1;
cudaSetDevice(gpuid_1);
cudaMalloc((void**)&dev_1, size);

//Check for peer access between participating GPUs:
int can_access_peer_0_1;
int can_access_peer_1_0;
cudaDeviceCanAccessPeer(&can_access_peer_0_1, gpuid_0, gpuid_1);
cudaDeviceCanAccessPeer(&can_access_peer_1_0, gpuid_1, gpuid_0);
printf("cudaDeviceCanAccessPeer(%d->%d): %d\n", gpuid_0, gpuid_1, can_access_peer_0_1);
printf("cudaDeviceCanAccessPeer(%d->%d): %d\n", gpuid_1, gpuid_0, can_access_peer_1_0);

if (can_access_peer_0_1 && can_access_peer_1_0) {
// Enable P2P Access
cudaSetDevice(gpuid_0);
cudaDeviceEnablePeerAccess(gpuid_1, 0);
cudaSetDevice(gpuid_1);
cudaDeviceEnablePeerAccess(gpuid_0, 0);
}

// Init Timing Data
uint32_t repeat = 10;
cudaEvent_t start;
cudaEvent_t stop;
cudaEventCreate(&start);
cudaEventCreate(&stop);

// Init Stream
cudaStream_t stream;
cudaStreamCreateWithFlags(&stream, cudaStreamNonBlocking);

// ~~ Start Test ~~
cudaEventRecord(start, stream);

//Do a P2P memcpy
for (int i = 0; i < repeat; ++i) {
cudaMemcpyAsync(dev_0, dev_1, size, cudaMemcpyDeviceToDevice, stream);
}

cudaEventRecord(stop, stream);
cudaStreamSynchronize(stream);
// ~~ End of Test ~~

// Check Timing & Performance
float time_ms;
cudaEventElapsedTime(&time_ms, start, stop);
double time_s = time_ms / 1e3;

double gb = size * repeat / (double)1e9;
double bandwidth = gb / time_s;

printf("Seconds: %f\n", time_s);
printf("Unidirectional Bandwidth: %f (GB/s)\n", bandwidth);

if (can_access_peer_0_1 && can_access_peer_1_0) {
// Shutdown P2P Settings
cudaSetDevice(gpuid_0);
cudaDeviceDisablePeerAccess(gpuid_1);
cudaSetDevice(gpuid_1);
cudaDeviceDisablePeerAccess(gpuid_0);
}

// Clean Up
cudaFree(dev_0);
cudaFree(dev_1);

cudaEventDestroy(start);
cudaEventDestroy(stop);
cudaStreamDestroy(stream);
}

some results

  • on H100
    Unidirectional Bandwidth: 253.631489 (GB/s)
  • on 4090
    Unidirectional Bandwidth: 25 (GB/s)

profiling

nsight compute: https://leimao.github.io/blog/Docker-Nsight-Compute/
cuda with docker: https://leimao.github.io/blog/NVIDIA-Docker-CUDA-Compatibility/

references

a deep dive into uniswap v3

concentrated liquidity

recap on AMM. the price of asset X is defined as
\[ \tag{1}
P = y/x
\]

where y is asset quantity of asset Y, and x is asset quantity of X.
since
\[ \tag{2}
L^{2} = x*y
\]
where \(L\) is the liquidity, and \(L^2=k\)

divide E.q.(2) by E.q.(1), we get
\begin{equation} \label{eq:3}
L/\sqrt{P} = x
\end{equation}

multiply E.q.(2) with E.q.(1), we get
\begin{equation} \label{eq:4}
L*\sqrt{P} = y
\end{equation}
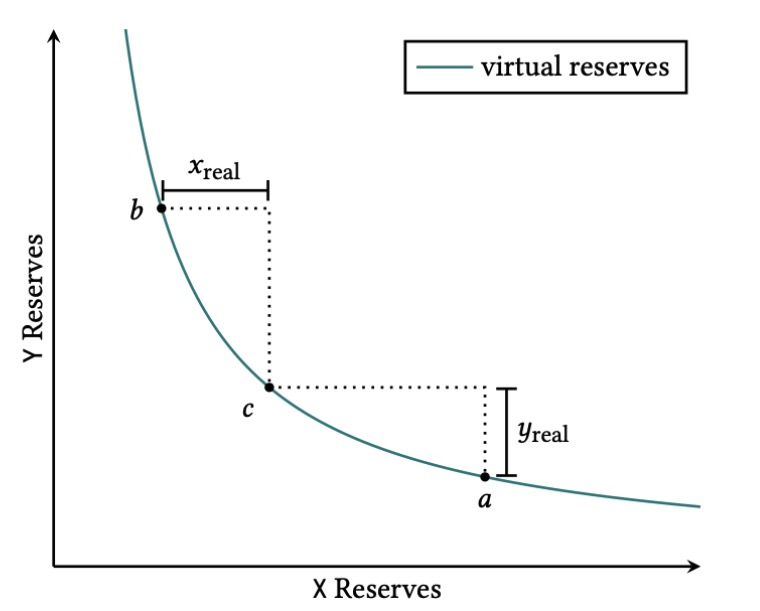
virtual reserves

at point a, we have
$$ L \cdot \sqrt{P_{a}} = y_{a} $$
at point b, we have
\[L/\sqrt{P_{b}} = x_{b}\]
at point c, we have
\begin{equation}
(x_{b} + x_{real}) * (y_{a}+y_{real}) = L^2
\end{equation}
then, we get
\begin{equation}
(L/\sqrt{P_{b}} + x_{real}) * (L*\sqrt{P_{a}}+y_{real}) = L^2
\end{equation}
which is E.q(2.2) in the original uni-v3 white paper

alternatively, liquidity can be thought of as the amount that token1(Y) reserves (either actual or virtual) changes for a given change in \(\sqrt{P}\)
\begin{equation}
L = \frac{\Delta Y}{\Delta\sqrt{P}}
\end{equation}

The global state also tracks the current tick index as tick $tick(i_{c})$, a signed integer representing the current tick (more specifically, the nearest tick below the current price)
specifically, at any given time, the following equation should be true:
\begin{equation}
i_{c} = \lfloor{log_{\sqrt{1.0001}}\sqrt{P}}\rfloor
\end{equation}

The global state also tracks two numbers: $feeGrowthGlobal0(f_{g,0})$ and $feeGrowthGlobal1(f_{g,1})$. These represent the total amount of fees that have been earned per unit of virtual liquidity $L$, over the entire history of the contract

Each tick tracks $\Delta L$, the total amount of liquidity that should be kicked in or out when the tick is crossed. The tick only needs to track one signed integer: the amount of liquidity added (or, if negative, removed) when the tick is crossed going left to right. This value does not need to be updated when the tick is crossed (but only when a position with a bound at that tick is updated)

polynomials

Introduction

Let \(A(X)\) be a polynomial over \(\mathbb{F}_p\) with formal indeterminate \(X\). As an example,

$$
A(X) = a_0 + a_1 X + a_2 X^2 + a_3 X^3
$$

defines a degree-\(3\) polynomial. \(a_0\) is referred to as the constant term. Polynomials of
degree \(n-1\) have \(n\) coefficients.

(aside) Horner’s rule

Horner’s rule allows for efficient evaluation of a polynomial of degree \(n-1\), using
only \(n-1\) multiplications and \(n-1\) additions. It is the following identity:
$$\begin{aligned}a_0 &+ a_1X + a_2X^2 + \cdots + a_{n-1}X^{n-1} \ &= a_0 + X\bigg( a_1 + X \Big( a_2 + \cdots + X(a_{n-2} + X a_{n-1}) \Big)!\bigg),\end{aligned}$$

Quotient Poly

  1. divide the evaluation in each point & use iFFT to get the poly coefficients
  2. or, could use polynomial long division

The Schwartz-Zippel lemma

The Schwartz-Zippel lemma informally states that “different polynomials are different at
most points.” Formally, it can be written as follows:

Let \(p(x_1, x_2, \cdots, x_n)\) be a nonzero polynomial of \(n\) variables with degree \(d\).
Let \(S\) be a finite set of numbers with at least \(d\) elements in it. If we choose random
\(\alpha_1, \alpha_2, \cdots, \alpha_n
\) from \(S\),
$$\text{Pr}[p(\alpha_1, \alpha_2, \cdots, \alpha_n) = 0] \leq \frac{d}{|S|}.$$

In the familiar univariate case \(p(X)\), this reduces to saying that a nonzero polynomial
of degree \(d\) has at most \(d\) roots.

The Schwartz-Zippel lemma is used in polynomial equality testing. Given two multi-variate
polynomials \(p_1(x_1,\cdots,x_n)\) and \(p_2(x_1,\cdots,x_n)\) of degrees \(d_1, d_2\)
respectively, we can test if
\(p_1(\alpha_1, \cdots, \alpha_n) - p_2(\alpha_1, \cdots, \alpha_n) = 0\) for random
\(\alpha_1, \cdots, \alpha_n \leftarrow S,\) where the size of \(S\) is at least
\(|S| \geq (d_1 + d_2).\) If the two polynomials are identical, this will always be true,
whereas if the two polynomials are different then the equality holds with probability at
most \(\frac{\max(d_1,d_2)}{|S|}\).

Vanishing polynomial

Consider the order-\(n\) multiplicative subgroup \(\mathcal{H}\) with primitive root of unity
\(\omega\). For all \(\omega^i \in \mathcal{H}, i \in [n-1],\) we have
\((\omega^i)^n = (\omega^n)^i = (\omega^0)^i = 1.\) In other words, every element of
\(\mathcal{H}\) fulfils the equation

$$
\begin{aligned}
Z_H(X) &= X^n - 1 \
&= (X-\omega^0)(X-\omega^1)(X-\omega^2)\cdots(X-\omega^{n-1}),
\end{aligned}
$$

meaning every element is a root of \(Z_H(X).\) We call \(Z_H(X)\) the vanishing polynomial
over \(\mathcal{H}\) because it evaluates to zero on all elements of \(\mathcal{H}.\)

This comes in particularly handy when checking polynomial constraints. For instance, to
check that \(A(X) + B(X) = C(X)\) over \(\mathcal{H},\) we simply have to check that
\(A(X) + B(X) - C(X)\) is some multiple of \(Z_H(X)\). In other words, if dividing our
constraint by the vanishing polynomial still yields some polynomial
\(\frac{A(X) + B(X) - C(X)}{Z_H(X)} = H(X),\) we are satisfied that \(A(X) + B(X) - C(X) = 0\)
over \(\mathcal{H}.\)

Lagrange basis functions

Polynomials are commonly written in the monomial basis (e.g. \(X, X^2, … X^n)\). However,
when working over a multiplicative subgroup of order \(n\), we find a more natural expression
in the Lagrange basis.

Consider the order-\(n\) multiplicative subgroup \(\mathcal{H}\) with primitive root of unity
\(\omega\). The Lagrange basis corresponding to this subgroup is a set of functions
\(\mathcal{L_i}_{i = 0}^{n-1}\)
where

$$
\mathcal{L_i}(\omega^j) = \begin{cases}
1 & \text{if } i = j, \
0 & \text{otherwise.}
\end{cases}
$$

We can write this more compactly as \(\mathcal{L_i}(\omega^j) = \delta_{ij},\) where
\(\delta\) is the Kronecker delta function.

Now, we can write our polynomial as a linear combination of Lagrange basis functions,

$$A(X) = \sum_{i = 0}^{n-1} a_i\mathcal{L_i}(X), X \in \mathcal{H},$$

which is equivalent to saying that \(A(X)\) evaluates to \(a_0\) at \(\omega^0\),
to \(a_1\) at \(\omega^1\), to \(a_2\) at \(\omega^2, \cdots,\) and so on.

When working over a multiplicative subgroup, the Lagrange basis function has a convenient
sparse representation of the form

$$
\mathcal{L}_i(X) = \frac{c_i\cdot(X^{n} - 1)}{X - \omega^i},
$$

where \(c_i\) is the barycentric weight. (To understand how this form was derived, refer to
[^barycentric].) For \(i = 0,\) we have
\(c = 1/n \implies \mathcal{L}_0(X) = \frac{1}{n} \frac{(X^{n} - 1)}{X - 1}\).

Suppose we are given a set of evaluation points \({x_0, x_1, \cdots, x_{n-1}}\).
Since we cannot assume that the \(x_i\)’s form a multiplicative subgroup, we consider also
the Lagrange polynomials \(\mathcal{L}_i\)’s in the general case. Then we can construct:

$$
\mathcal{L}i(X) = \prod{j\neq i}\frac{X - x_j}{x_i - x_j}, i \in [0..n-1].
$$

Here, every \(X = x_j \neq x_i\) will produce a zero numerator term \((x_j - x_j),\) causing
the whole product to evaluate to zero. On the other hand, \(X= x_i\) will evaluate to
\(\frac{x_i - x_j}{x_i - x_j}\) at every term, resulting in an overall product of one. This
gives the desired Kronecker delta behaviour \(\mathcal{L_i}(x_j) = \delta_{ij}\) on the
set \({x_0, x_1, \cdots, x_{n-1}}\).

Lagrange interpolation

Given a polynomial in its evaluation representation

$$A: {(x_0, A(x_0)), (x_1, A(x_1)), \cdots, (x_{n-1}, A(x_{n-1}))},$$

we can reconstruct its coefficient form in the Lagrange basis:

$$A(X) = \sum_{i = 0}^{n-1} A(x_i)\mathcal{L_i}(X), $$

where \(X \in {x_0, x_1,\cdots, x_{n-1}}.\)

references

multi scalar multiplication (MSM)

Problem

Let \( \mathbb{G}\) be a group of order \(p=2^{\lambda}\)(\(\lambda\) would be the number of bits of the prime). Give \(n\) scalars \(e_i\) and \(n\) EC points \(P_i\), calculate \(P\) such that
\[ P = \sum_{i=0}^{n}e_i P_i \]

naive approach

Let \(e_i = e_{i,\lambda -1} e_{i,\lambda -2} …e_{i,0} \), where each \(e_{i,j} \in 0,1\).
We have
\[ e_i = e_{i,\lambda-1}\cdot2^{\lambda-1} + e_{i, \lambda-2}\cdot2^{\lambda-2} + …+e_{i,0}\cdot2^0\]
To compute \(e_i \cdot p_i\), we can compute \(2^0 \cdot p_i,2^1 \cdot p_i,…,2^{\lambda-1} \cdot p_i \). Then, we simply add them up to get \(e_i \cdot p_i\). Here, we need \(\lambda -1\) squarings (multiplication by 2) and \(\lambda-1\) additions.
To computing \(e_1\cdot p_1, e_2 \cdot p_2, …, e_{N-1}\cdot p_{N-1}\), we need \(N\cdot(\lambda-1)\) squarings and \(N\cdot(\lambda-1)\) additions.

We additionally need \(N-1\) additions to sum \(e_i\cdot p_i\) into \(P\).
In total, weed \(N\cdot(\lambda-1)\) squarings and \(N\cdot\lambda=1\) additions

pippenger approach

at a high level, Pippenger approach divides \(\lambda\) bits into num_window (\(=\frac{\lambda}{c}\)) bit windows where each bit window has \(c\) bits. \(c\) is also called “window size”.

Part I (computation for each window)

Initialize a vector window_res = [0,0,...,0] of length num_window.
For the w-th window:

  • Initialize a vector buckets=[0,0,...,0] of length num_buckets = \( 2^c -1 \).
  • Get the start_idx of the current window, say \(M\). Remember that we are considering a c-bit window out of \(\lambda\)-bit fields
  • for each pair of \((e_i, g_i)\)
    • Get the bits in scalar \(e_i\) correspondign to the current window. Formally, we have scalar = \((e_i >> M) \mod 2^c\).
    • If scalar \(\ne 0\), we have buckets[scalar-1] += \(p_i\)
  • Initialize tmp = 0
  • For j in \(2^c-1\) to 1:
    tmp= tmp+buckets[j]
  • window_res[w] = tmp

Part II (sum over all windows)

1
2
3
4
5
6
7
lowest = window_res[0]
total = 0
for w in num_window -1 to 1:
total += window_res[w]
for _ in 0..c:
total = total + total // shift left c bits.
total = total + lowest

total is the final result

In Part I, for each window, we need \(N+2^c\) additions. Since we have \(\frac{\lambda}{c}\) windows, we need \((N+2^{\lambda}*\frac{\lambda}{c})\) additions.

In Part II, we need 1 addition and c squarings for each window.
In total, we need \(\frac{\lambda}{c}\cdot(N+2^c+1)\) additions and \(\lambda\) squarings.

In Arkworks implementation, c is set to be \(ln(N)+2\).
For notation simplicity, let’s set c to be \(log2(N)\). Then, the computation complexity of Pippenger’s algorithm is \(\frac{2N\lambda}{log2(N)}+1\) additions and \(\lambda\) squarings
Since \(\lambda\) is a constant for a elliptic curve, people usually say that pippenger has a time complexity of \(O(\frac{N}{log(N)})\)

References

cpp build

cmake

environment variables

  • CMAKE_SOURCE_DIR: the root directory of the source tree for the project. This variable holds the full path to the directory where the top-level CMakeLists.txt file is located.
1

system config

  • /etc/ld.so.conf
    The file /etc/ld.so.conf is a configuration file used by the dynamic linker/loader on Unix-like systems, including Linux. Its purpose is to specify additional directories where the linker should search for shared libraries at runtime.
    When a program starts, the dynamic linker/loader is responsible for resolving and loading shared libraries (also known as dynamic libraries or shared objects). The paths specified in /etc/ld.so.conf help the linker locate these libraries.
    On some systems, you might also find additional configuration files in the /etc/ld.so.conf.d/ directory, each containing a list of directories.
    After modifying the file, you need to run the ldconfig command to update the dynamic linker’s cache and apply the changes.

note: ld stands for linker

tools

nm

nm is a command-line utility on Unix-like operating systems that displays information about the symbols (e.g., functions, variables) contained in object files, executables, and shared libraries. The name “nm” stands for “name list.”

1
nm -D ${path_to_dynamic_library}

The default information that the ‘nm’ command provides is :

  • Virtual address of the symbol
  • A character which depicts the symbol type. If the character is in lower case then the symbol is local but if the character is in upper case then the symbol is external
  • Name of the symbol

The characters that identify symbol type describe :

  • A : Global absolute symbol.
  • a : Local absolute symbol.
  • B : Global bss symbol.
  • b : Local bss symbol.
  • D : Global data symbol.
  • d : Local data symbol.
  • f : Source file name symbol.
  • L : Global thread-local symbol (TLS).
  • l : Static thread-local symbol (TLS).
  • T : Global text symbol.
  • t : Local text symbol.
  • U : Undefined symbol.

objdump

environment variables

  • LD_LIBRARY_PATH
    The LD_LIBRARY_PATH environment variable is used in Unix-like operating systems (including Linux) to specify a list of directories where the system should look for shared libraries before searching the default system locations. This variable is particularly useful when you want to run an executable that depends on shared libraries that are not in standard library paths.
  1. compiling
    1
    g++ -o my_program my_program.cpp -lmy_library -L/path/to/library
  2. running
    1
    2
    export LD_LIBRARY_PATH=/path/to/library:$LD_LIBRARY_PATH
    ./my_program

field

Pseudo-Mersenne Prime

Pseudo-Mersenne Prime is a prime of the form
\[ p = 2^m -k \]
where \(k\) is an integer for which
\[ 0 \lt |k| \lt 2^{\lfloor m/2 \rfloor} \]

if \(k=1\), then \(p\) is a Mersenne prime (and \(m\) must necesarily be a priime). if \(k=-1\); then \(p\) is called a Fermat prime (and \(m\) must necessarily be a power of two)

Pseudo-Mersenne primes are useful in public-key cryptography because they admit fast modular reduction similar to Mersenne primes. If \(n\) is a positive integer less than \(p^2\), then \(n\) can be written as
\[ n = u \cdot 2^{2m} + a \cdot 2^{m} + b \]
where \(u=0\) or \(1\) and \(a\) and \(b\) are nonnegative integers less than \(2^m\). Then
\[ n \equiv u \cdot k^2 + a \cdot k + b \mod p\]

Repeating this substitution a few times will yield \(n \mod p\).

Optimal Extension Fields (OEF)

Optimal extension fields (OEFs) are a family of finite fields with an arithmetic that can be implemented efficiently in software. OEFs are extension fields \(GP(p^m)\) where the prime p is of special form.

An Optimal Extension Field is a finite field \(GF(p^m)\) such that

  1. \(p\) is pseudo Mersenne prime
  2. An irreducible binomial \(P(x) = x^m - \omega\) exists over \(GF(p)\)

other concepts

two adicity

A two-adicity of 32 means that there’s a multiplicative subgroup of size \(2^32\) that exists in the field.
For example

1
2
3
4
const TWO_ADICITY: u32 = 32;
const TWO_ADIC_ROOT_OF_UNITY: BigInteger = BigInteger([
0x218077428c9942de, 0xcc49578921b60494, 0xac2e5d27b2efbee2, 0xb79fa897f2db056
]); // TWO_ADIC_ROOT_OF_UNITY^{2^32} = 1

references

  • Pseudo-Mersenne Prime
  • [Optimal Extension Field] Bailey DV, Paar C (1998) Optimal extension fields for fast arithmetic in public-key algorithms. In: Krawczyk H (ed), Advances in cryptology–CRYPTO ’98, LNCS 1462. Springer, Berlin, pp 472–485