polygon zkEVM

zkProver

State Machines

The zkProver follows modularity of design to the extent that, except for a few components, it is mainly a cluster of State Machines. It has a total of thirteen (13) State Machines;

  • The Main State Machine
  • Secondary State Machines → Binary SM, Storage SM, Memory SM, Arithmetic SM, Keccak Function SM, PoseidonG SM,
  • Auxiliary State Machines → Padding-PG SM, Padding-KK SM, Bits2Field SM, Memory Align SM, Byte4 SM, ROM SM.
    Due to the modular design of zkProver, the Main State Machine can delegate as many of tasks as possible to other specialist State Machines. This heavily improves the efficiency of Main SM.

Two Novel Languages For zkProver

Zero-Knowledge Assembly(zkASM)

As an Assembly language, the Zero-Knowledge Assembly (or zkASM) language is specially designed to map instructions from the zkProver’s Main State Machine to other State Machines. In case of the State Machines with firmware, zkASM is the Interpreter for the firmware.

Polynomial Identity Language(PIL)

The Polynomial Identity Language (or PIL) is especially designed for the zkProver. Almost all state machines express computations in terms of polynomials. Therefore, state transitions in State Machines must satisfy computation-specific polynomial identities.

Microprocessor State Machines

There are two microprocessor-type state machines; the Main SM and the Storage SM. These two State Machines have the Firmware and the Hardware part. It is worth noting that each of these Microprocessor SM has its own ROM.

The Firmware part runs the zkASM language to set up the logic and rules, which are expressed in JSON format and stored in a ROM. The JSON-file is then parsed to the specific SM Executor, which executes Storage Actions in compliance with the rules and logic in the JSON-file.

The Hardware component, which uses the Polynomial Identity Language (PIL), defines constraints (or polynomial identities), expresses them in JSON format, and stores them in the accompanying JSON-file. These constraints are parsed to the specific SM Executor, because all computations must be executed in conformance to the polynomial identities.

montgomery multiplication

montgomery space

Montgomery multiplication works by first transforming the multipliers into Montgomery space, where modular multiplication can be performed cheaply, and then transforming them back when their actual values are needed. Unlike general integer division methods, Montgomery multiplication is not efficient for performing just one modular reduction and only becomes worthwhile when there is a chain of modular operations.

The space is defined by the modulo n and a positive integer r ≥ n coprime to n. The algorithm involves modulo and division by r, so in practice, r is chosen to be 2^32 or 2^64, so that these operations can be done with a right-shift and a bitwise AND respectively.

Definition. the representative \(\bar{x}\) of a number \(x\) in the Montgomery space is defined as
\[ \bar{x} = x \cdot r \mod n \]

Computing this transformation involves a multiplication and a modulo — an expensive operation that we wanted to optimize away in the first place — which is why we only use this method when the overhead of transforming numbers to and from the Montgomery space is worth it and not for general modular multiplication.

Inside the Montgomery space, addition, substraction, and checking for equality is performed as usual:

\[ x \cdot r + y \cdot r \equiv (x+y) \cdot r \mod n \]

However, this is not the case for multiplication. Denoting multiplication in the Montgomery space as \(∗\) and the “normal” multiplication as \(\cdot\), we expect the result to be:
\[ \bar{x} * \bar{y} = \overline{x\cdot y} = (x\cdot y)\cdot r \mod n \]

But the normal multiplication in the Montgomery space yields:
\[ \bar{x} \cdot \bar{y}=(x\cdot y)\cdot r \cdot r \mod n \]

Therefore, the multiplication in the Montgomery space is defined as
\[ \bar{x} * \bar{y} = \bar{x} \cdot \bar{y} \cdot r^{-1} \mod n \]

This means that, after we normally multiply two numbers in the Montgomery space, we need to reduce the result by multiplying it by \(r^{-1}\) and taking the modulo — and there is an efficent way to do this particular operation.

Montgomery reduction

assume that \(r=2^{32}\), the modulo \(n\) is 32-bit, and the number \(x\) we need to reduce is 64-bit(the product of two 32-bit numbers). The goal is to calculate \(y=x\cdot r^{-1} \mod n\).

Since \(r\) is coprime with \(n\), we know that there are two numbers \(r^{-1}\) and \(n’\) in the \([0, n)\) range such that
\[ r \cdot r^{-1} + n \cdot n’ = 1 \]
both \(r^{-1} and \quad n’\) can be computed using extended Euclidean algorithm (\(n’ = n^{-1} \mod r\)).
Using this identiy, we can express \(r \cdot r^{-1}\) as \(1-n\cdot n’\) and write \(x \cdot r^{-1}\) as

\[
\displaylines{
x\cdot r^{-1} = \frac{x \cdot r \cdot r^{-1}}{r} \\
= \frac{x \cdot (1-n\cdot n’)}{r} \\
= \frac{x - x \cdot n \cdot n’}{r} \\
= \frac{x - x \cdot n \cdot n’ + k\cdot r \cdot n}{r} \quad (\mod n) (for \hspace{0.2cm}any\hspace{0.2cm} integer\hspace{0.2cm} k) \\
= \frac{x - (x\cdot n’ - k\cdot r)\cdot n}{r}
}
\]

Now, if we choose \(k\) to be \(\lfloor x\cdot n’/r\rfloor\) (the upper 64 bits of \(x\cdot n’\), giving \(x\) is 64 bits and \(n’\) is 32 bits ), it will cancel out, and \(k\cdot r - x\cdot n’\) will simply be equal to \(x \cdot n’ \mod r\) (the lower 32 bits of \(x\cdot n’\)), implying:
\[ x\cdot r^{-1} = (x - (x\cdot n’ \mod r )\cdot n)/r\]

the algorithm itself just evaluates this formula, performing two multiplications to calculate \(q = x\cdot n’ \mod r\) and \(m = q\cdot n\), and then subtracts it from \(x\) and right shifts the result to divide it by r.

The only remaining thing to handle is that the result may not be in the \([0,n)\) range; but since
\[x < n\cdot n < r\cdot n => x/r < n \]
and
\[m = q\cdot n < r\cdot n => m/r < n\]
it is guaranted that
\[ -n < (x-m)/r < n \]

Therefore, we can simply check if the result is negative and in that case, add \(n\) to it, giving the following algorithm:

1
2
3
4
5
6
7
8
9
10
11
typedef __uint32_t u32;
typedef __uint64_t u64;

const u32 n = 1e9 + 7, nr = inverse(n, 1ull << 32); // nr is n' in the above equations, r is 1<<32

u32 reduce(u64 x) {
u32 q = u32(x) * nr; // q = x * n' mod r
u64 m = (u64) q * n; // m = q * n
u32 y = (x - m) >> 32; // y = (x - m) / r
return x < m ? y + n : y; // if y < 0, add n to make it be in the [0, n) range
}

This last check is relatively cheap, but it is still on the critical path. If we are fine with the result being in the \([0,2\cdot n−2]\) range instead of \([0, n)\), we can remove it and add \(n\) to the result unconditionally:

1
2
3
4
5
6
u32 reduce(u64 x) {
u32 q = u32(x) * nr;
u64 m = (u64) q * n;
u32 y = (x - m) >> 32;
return y + n
}

We can also move the >> 32 operation one step earlier in the computation graph and compute \(\lfloor x/r \rfloor - \lfloor m/r \rfloor\) instead of \( (x-m)/r\). This is correct because the lower 32 bits of \(x\) and \(m\) are equal anyway since
\[ m = x\cdot n’ \cdot n = x \mod r\] (mod r is same as taking the lower 32 bits).

But why would we voluntarily choose to perfom two right-shifts instead of just one? This is beneficial because for ((u64) q * n) >> 32 we need to do a 32-by-32 multiplication and take the upper 32 bits of the result (which the x86 mul instruction already writes in a separate register, so it doesn’t cost anything), and the other right-shift x >> 32 is not on the critical path.

1
2
3
4
5
u32 reduce(u64 x) {
u32 q = u32(x) * nr;
u32 m = ((u64) q * n) >> 32;
return (x >> 32) + n - m;
}

if to reduce a u128 number(u64 * u64). it is as below

1
2
3
4
5
6
7
typedef __uint128_t u128;

u64 reduce(u128 x) const {
u64 q = u64(x) * nr;
u64 m = ((u128) q * n) >> 64;
return (x >> 64) + n - m;
}

Faster Inverse

Montgomery multiplication itself is fast, but it requires some precomputation:

  • inverting \(n\) modulo \(r\) to compute \(n’\)
  • transforming a number to the Montgomery space,
  • transforming a number from the Montgomery space.

The last operation is already efficiently performed with the reduce procedure we just implemented, but the first inverting can be slightly optimized.
Computing the inverse \(n’ = n^{-1} \mod r\) can be done faster than with the extended Euclidean algorith by taking advantage of the fact that \(r\) is a power of two and using the following identity:
\[ a\cdot x = 1 \mod 2^k => a\cdot x\cdot (2-a\cdot x) = 1 \mod 2^{2k} \]
Proof:
\[
\displaylines{
a\cdot x \cdot (2-a\cdot x) = 2\cdot a\cdot x - (a\cdot x)^2 \\
= 2\cdot(1+m\cdot 2^k) - (1+m\cdot 2^k)^2 \\
= 2 + 2\cdot m\cdot 2^k - 1-2\cdot m \cdot 2^k -m^2\cdot 2^{2k} \\
= 1-m^2\cdot 2^{2k} \\
= 1 \mod 2^{2k}
}
\]
note

  • \(a\cdot x \) coudl be represented by \(1+m\cdot 2^k\) as \(a\cdot x = 1 \mod 2^k\)

as for our case, \(x\) is \(nr\), \(a\) is \(n\). i.e \(n\cdot nr = 1 \mod 2^k\). Since \(n \) is an odd number, we can start with \(nr=1\) as the inverse of \(n\) modulo \(2^1\). then applying this identity one time, i.e \(n\cdot 1 \cdot (2-n\cdot 1) = 1 \mod 2^2\). Let \(nr = 1\cdot(2-n\cdot 1) \), we apply this identity again, and get \(n\cdot nr \cdot (2-a\cdot nr) = 1 \mod 2^4\). Following this approach, and apply this identity exactly \(log_2^m\) times, where \(m\) is the bit length of \(r\)

Complement Implementation

1
2


references

kzg polynomial commitment

introduction

KZG polynomial commitments was introduced by Kate, Zaverucha and Goldberg. It is called a commitment, because having sent the commitment value (an elliptic curve point) to someone (the verifier), the prover cannot change the polynomial they are working with.

Comparison to Merkle trees

A Merkle tree is what cryptographers call a vector commitment: Using a Merkle tree of depth \(d\), you can compute a commitment to a vector. A polynomial commitment can be achived by making a merkle tree commitment of all polynomials coefficients. however, it is not efficient.

parings

Let \(\mathbb{G_1}\) and \(\mathbb{G_2}\) be two elliptic curves wit a paring \(e: \mathbb{G_1} \times \mathbb{G_2} \rightarrow \mathbb{G_T}\). Let \(p\) be the order of \(\mathbb{G_1}\) and \(\mathbb{G_2}\), and \(G\) and \(H\) be generators of \(\mathbb{G_1}\) and \(\mathbb{G_2}\). We will use a very useful shorhand notation
\( [x]_1 = xG \in \mathbb{G_1}\), and \([x]_2 = xH \in \mathbb{G_2} \), for any \(x \in \mathbb{F_p}\)

Trusted setup

Let’s assume we have a trusted setup, so that for some secret \(s\), the elements \([s^i]_1\) and \([s^i]_2\) are available to both prover and verifier for \(i=0, …, n-1\).

Let \(p(X) = \sum_{i=0}^{n}p_i X^i \) be a polynomial, the prover can compute

\( \left[ p(s) \right]_1 = p_0[s^0]_1 + p_1[s^1]_1 + … + p_n[s^n]_1 \)

Kate commitment

In the Kate commitment scheme, the eleemnt \(C = [p(s)]_1\) is the commitment to the polynomial \(p(X)\). Could the prover (without knowing \(s\)) find another polynomial \(q(X) \neq p(X)\) that has the same commitment. Let’s assume that this were the case. Then it would mean \([p(s) - q(s)]_1 = 0\), implying \(p(s) - q(s) = 0\).

Now, \(r(X) = p(X) - q(X)\) is itself a polynomial. we know that it’s not constant because \(p(X) \neq q(X) \). It is a well-known fact that any non-constant polynomial of degree \(n\) can have at most \(n\) zeroes.
Since the prover doesn’t know \(s\), the only way they could achieve that \(p(s) - q(s) = 0\)
is by making \( p(X) - q(X)=0\) in as many places as possible. But since they can do that in at most \(n\)
places, as we’ve just proved, they are very unlikely to succeed: since \(n\) is much smaller than the order of the curve, \(p\). the probability that \(s\) will be one of the points they chose to make \(p(X) = q(X)\) will be vanishingly tiny.

Multiplying polynomials

While elliptic curves themselves don’t allow polynomial multiplication, luckily we can do it with pairings: We have that
\[ e([a]_1, [b]_2) = e(G,H)^{(ab)} = [ab]_T\]
while we unfortunately can’t just multiply two field elements inside an elliptic curve and get their product as an elliptic curve element, we can multiply two field elements if we commited to them in different curves (one in \(G_1\) and one in \(G_2\), and the output is a
\(G_T\) element.

Noe let’s say we want to prove that \(p(z)=y\). we will use the polynomial \(p(X) - y\). this polynomial is clearly zero at \(z\). Let \(q(X)\) be the polynomial \(p(X) - y\) divided by the linear factor \(X-z\), i.e
\[ q(X) = \frac{p(X) - y}{X-z} \]
which is equivalent to saying that \(q(X)(X-z) = p(X) - y\)

Kate proofs

now a kate proof for the evaluation \(p(z) = y\) is defined as \(\pi = [q(s)]_1\). remember the commitment to the polynomial \(p(X)\) is defined as \(C=[p(s)]_1\)
the verifier checks this proof using the following equation
\( e(\pi, [s-z]_2) = e(C-[y]_1, H) \)

Note that the verifier can compute \([s-z]_2\), because it is just a combination of the element \([s]_2\)
from the trusted setup and \(z\) is the point at which the polynomial is evaluated.

multiproofs

So far we have shown how to prove an evaluation of a polynomial at a single point. Note that this is already pretty amazing: You can show that some polynomial that could be any degree – say \(2^{28}\) – at some point takes a certain value, by only sending a single group element (that could be 48 bytes, for example in BLS12_381). The toy example of using Merkle trees as polynomial commitments would have needed to send \(2^{28}\) elements – all the coefficients of the polynomial.

Let’s say we have a list of \(k\) points \((z_0, y_0),(z_1, y_1), …, (z_{k-1}, y_{k-1})\). Using lagrange interpolation, we can find polynomial \(I(X)\) goes through all of these points.

Now let’s assume that we know \(p(X)\) goes through all these points. then the polynomial \(p(X) - I(X)\) will clearly be zero at each \(z_0, z_1, …, z_{k-1}\). the zero polynomial is
\(Z(X) = (X-z_0)\cdot (X-z_1)…(X-z_{k-1})\)
Now, we can compute the quotient
\(q(X) = \frac{p(X)-I(X)}{Z(X)}\)
We can now define the Kate multiproof for the evaluations \((z_0, y_0),(z_1, y_1),…, (z_{k-1}, y_{k-1})\): \(\pi = [q(s)]_1\). note that this is still only one group element.

Now, to check this, the verifier will also have to compute the interpolation polynomial \(I(X)\) and the zero polynomial Z(X). Using this, they can compute \([Z(s)]_2\) and \([I(s)]_1\), and thus verify the paring equation
\[ e(\pi, [Z(s)]_2) = e(C-[I(s)]_1, H) \]

Kate as a vector commitment

While the Kate commitment scheme is designed as a polynomial commitment, it actually also makes a really nice vector commitment. Remember that a vector commitment commits to a vector \(a_0, …, a_{n-1}\) and lets you prove that you committed to \(a_i\) for some \(i\). We can reproduce this using the Kate commitment scheme: Let \(p(X)\) be the polynomial that for all \(i\) evaluates as \(p(i)=a_i\).
Now using this polynomial, we can prove any number of elements in the vector using just a single group element! Note how much more efficient (in terms of proof size) this is compared to Merkle trees

references

Dankrad Feist Post

bls12_381

introduction

BLS12-381 is a pairing-friendly elliptic curve. Curve BLS12-381 was designed by Sean Bowe in early 2017 as the foundation for an upgrade to the Zcash protocol. It is both pairing-friendly (making it efficient for digital signatures) and effective for constructing zkSnarks. BLS12-381 is part of a family of curves described by Barreto, Lynn, and Scott (BLS). The 12 is the embedding degree of the curve: neither too low, nor too high. The 381 is the number of bits needed to represent coordinates on the curve: the field modulus, \(q\). 381 is a fairly handy number as we can use 48 bytes per field element, with 3 bits left over for useful flags or arithmetic optimisations. This size of this number is guided both by security requirements and implementation efficiency.

curve equation and parameters

The basic equation of the BLS12-381 curve is \( y^2 = x^3 + 4\)
The key parameters for a BLS curve are set using a single parameter \(\mathbf{x}\) (different from the in the curve equation!). BLS12-381 is derived from the \( k \equiv 0 \mod 6\) case of Construction 6.6 in the taxonomy.

Specific design goals for BLS12-381 are:

  • \(\mathbf{x}\) has “low hamming weight”, meaning that it has very few bits set to 1. This is particularly important for the efficiency of the algorithm that calculates pairings (the Miller loop).
  • The field modulus \(q\) mentioned above is prime and has 383 bits or fewer, which makes 64-bit or 32-bit arithmetic on it more efficient.
  • The order \(r\) of the subgroups we use is prime and has 255 bits or fewer, which is good for the same reason as above.
  • To support zkSnark schemes, we want to have a large power of two root of unity in the field. This means we want \(2^n\) to be a factor of \(r-1\), for some biggish \(n\). (Making \(\mathbf{x}\) a multiple of \(2^{n/2}\) will achieve this.) This property is key to being able to use fast Fourier transforms for interesting things like polynomial multiplication.

The value \(\mathbf{x}\) = -0xd201000000010000 (hexadecimal, note that it is negative) gives the largest and the lowest Hamming weight meeting these criteria. With this value we have,

parameters equation value(hex) comments
Field modulus \(q\) \(\frac{1}{3}(\mathbf{x}-1)^2(\mathbf{x}^4-\mathbf{x}^2+1) + \mathbf{x}\) 0x1a0111ea397fe69a4b1ba7b6434bacd764774b84f3
8512bf6730d2a0f6b0f6241eabfffeb153ffffb9feffffffffaaab
381 bits, prime
Subgroup size \(r\) \((\mathbf{x}^4-\mathbf{x}^2+1)\) 0x73eda753299d7d483339d80809a1d80553
bda402fffe5bfeffffffff00000001
255 bits, prime

Field extensions

Field extensions are fundamental to elliptic curve pairings. The “12” is BLS12-381 is not only the embedding degree, it is also (relatedly) the degree of field extension that we will need to use.
For example, The complex numbers are a quadratic extension of the real numbers (\(x^2 = 1\)). Complex numbers can’t be extended any further because there are no irreducible polynomials over the complex numbers. But for finite fields, if we can find an irreducible \(k\)-degree polynomial in our field \(F_q\), and we often can, then we are able to extend the field to \(F_{q^k}\), , and represent the elements of the extended field as degree \(k-1\) polynomials, \(a_0 + a_1 x + … + a_{k-1}x^{k-1}\). we can represent this compactly as (\(a_0, a_1, …, a_{k-1}\))
In practice, large extension fields like \(F_{q^{12}}\)are implemented as towers of smaller extensions.

the curves

BLS12-381 is really dealing with two curves. Both curves share more-or-less the same curve equation, but are defined over different fields.
The simpler one is over the finite field \(F_q\), which is just the integers mod \(q\). So the curve has points only where the equation \(y^2 = x^3 +4\) has solutions with \(x\) and \(y\) both integers less than \(q\). We shall call this curve \(E(F_q)\).
The other curve is defined over an extension of \(F_q\)to \(F_{q^2}\) (think complex numbers). In this case, the curve equation is slightly modified to be \(y^2 = x^3+4(1+i)\), and we call the curve \(E’(F_{q^2})\)

the subgroups

A pairing is a bilinear map. This means that it takes as input two points, each from a group of the same order, \(r\). for rather technical reasons, these two groups need to be distinct. Let’s call them
\(G_1\) and \(G_2\).
Unfortunately, our simple curve \(E(F_q)\) has only a single large subgroup of order \(r\), so we can’t define a pairing based solely on \(E(F_q)\). However, if we keep extending the field over which
\(E\) is defined, it can be proved that we eventually find a curve that has more than one subgroup of order \(r\). that is, for some \(k\), \(E(F_{q^k})\) contains other subgroups of order \(r\) that we can use. One of these subgroups contains only points having a trace of zero[1], and we choose that subgroup to be \(G_2\)

This number \(k\), the amount that we need to extend the base field by to find the new group, is called the embedding degree of the curve, which in our case is the “12” in BLS12-381. For completeness, note that each of \(G_1\) and \(G_2\) shares with its containing curve the “point at infinity”. This is the identity element of the elliptic curve arithmetic group, often denoted \(\mathcal O\)
. For any point \(P\), \( P + \mathcal O = \mathcal O + P = P\).

Twists

But there’s another challenge. As discussed earlier, doing arithmetic in \(F_{q^{12}}\) is horribly complicated and inefficient. And curve operations need a lot of arithmetic. A twist is something like a coordinate transformation. Rather wonderfully, this can be used to transform our \(E(F_{q^{12}})\) curve into a curve defined over a lower degree field that still has an order \(r\) subgroup. Moreover, this subgroup has a simple mapping to and from our \(G_2\) group

BLS12-381 uses a “sextic twist”. This means that it reduces the degree of the extension field by a factor of six. So \(G_2\) on the twisted curve can be defined over \(F_{q^2}\) instead of \(F_{q^{12}}\)
I haven’t seen this written down anywhere—but attempting to decode section 3 of this—if we find a \(u\) such that \(u^6 = (1+i)^{-1}\), then we can define our twisting transformation as \( (x,y) -> (x/u^2, y/u^3)\). This transforms our original curve \(E: y^2 = x^3 + 4\) into the curve \(E’: y^2 + 4/u^6 = x^3 + 4(1+i)\). \(E\) and \(E’\) look different, but are actually the same object presented with respect to coefficinets in different base fields.

So these are the two groups we will be using:

  • \(G_1 \subset E(F_q)\), where \(E: y^2 = x^3 + 4\)
  • \(G_2 \subset E(F_{q^2})\), where \(E: y^2 = x^3 + 4(1+i)\)
    Note that coordinates of points in the \(G_1\) group are pairs of integers, and coordinates of points in the \(G_2\) group are pairs of complex integers.

Parings

s far as BLS12-381 is concerned, a pairing simply takes a point \(P \in G_1 \subset E(F_q)\), and a point \(Q \in G_2 \subset E’(F_{q^2})\) and outputs a point from a group \(G_T \subset F_{q^{12}}\). That is, for a paring \(e\), \(e: G_1 \times G_2 \rightarrow G_T\)

properties of pairing
\( e(P, Q+R) = e(P,Q) \cdot e(P,R) \),
note as a way of memory, can think it as \(P^{Q+R} = P^Q \cdot P^R\)
\( e(P+S, R) = e(P,R) \cdot e(S,R)\)
From this, we can deduce that all of the following identities hold:
\(e([a]P, [b]Q) = e(P, [b]Q)^a = e(P,Q)^{ab} = e(P, [a]Q)^b = e([b]P, [a]Q)\)

Embedding degree

The embedding degree, \(k\), is calculated as the smallest positive integer such that \(r\) divides \(q^k -1\). So, in the case of BLS12-381, \(r\) is a factor of \(q^{12} -1\), but not of any lower power.
The choice of an embedding degree is a balance between security and efficiency (as ever). On the security front, the embedding degree is also known as the security multiplier: a higher embedding degree makes the discrete logarithm problem harder to solve in
. However, a high embedding degree means we have to do field operations in high-degree extensions, which is clunky and inefficient.

cofactor

A subgroup’s cofactor is the ratio of the size of the whole group to the size of the subgroup.

Group Cofactor Equation value(hex)
\(G_1\) \(h_1\) \(\frac{\mathbf{x-1}^2}{3}\) 0x396c8c005555e
1568c00aaab0000aaab
\(G_2\) \(h_2\) \(\frac{\mathbf{x}^8 -4\mathbf{x}^7+5\mathbf{x}^6-4\mathbf{x}^4+6\mathbf{x}^3-4\mathbf{x}^2-4\mathbf{x}+13}{9}\) 0x5d543a95414e7f1091d50792876a202cd91de
4547085abaa68a205b2e5a7ddfa628f1cb4d9e82ef2
1537e293a6691ae1616ec6e786f0c70cf1c38e31c7238e5

note multiplying by the cofactor turns out to be a straightforward way to map any arbitrary point on the elliptic curve into the respective subgroup \(G_1\) or \(G_2\)

Generators

\(G_1\) and \(G_2\) are cyclic groups of prime order, so any point (except the identity/point at infinity) is a generator. Thus, picking generators is just a matter of convention.
Generator points \(G_1\) and \(G_2\) are specified in decimal here

These were chosen as follows:

The generators of \(G_1\) and \(G_2\) are computed by finding the lexicographically smallest valid x-coordinate, and its lexicographically smallest > y-coordinate and scaling it by the cofactor such that the result is not the point at infinity.

Foot notes

[1] The “trace zero subgroup” qualifies as an obscure incantation. Basically, the trace of a point is \(\sum_{i=0}^{k-1}(x^{q^i}, y^{q^i})\), where \(k=12\) in our case. Understanding this involves stuff like the Frobenius endomorphism.

references

key concepts in cuda

key concepts

  • Warps: In CUDA, a warp is a fundamental execution unit in the GPU. It represents a group of threads that are executed together in a SIMD (Single Instruction, Multiple Data) fashion on a single GPU core. In CUDA, each group of 32 consecutive threads is called a warp. A Warp is the primary unit of execution in an SM. Once a thread block is allocated to an SM, it will be further divided into a set of warps for execution.
  • Stream Multiprocessor (SM)
    The CUDA architecture is built around a scalable array of multithreaded Streaming Multiprocessors (SMs). When a CUDA program on the host CPU invokes a kernel grid, the blocks of the grid are enumerated and distributed to multiprocessors with available execution capacity. The threads of a thread block execute concurrently on one multiprocessor, and multiple thread blocks can execute concurrently on one multiprocessor. As thread blocks terminate, new blocks are launched on the vacated multiprocessors
    Each SM contains 8 CUDA cores, and at any one time they’re executing a single warp of 32 threads - so it takes 4 clock cycles to issue a single instruction for the whole warp. You can assume that threads in any given warp execute in lock-step, but to synchronise across warps, you need to use __syncthreads()

memory

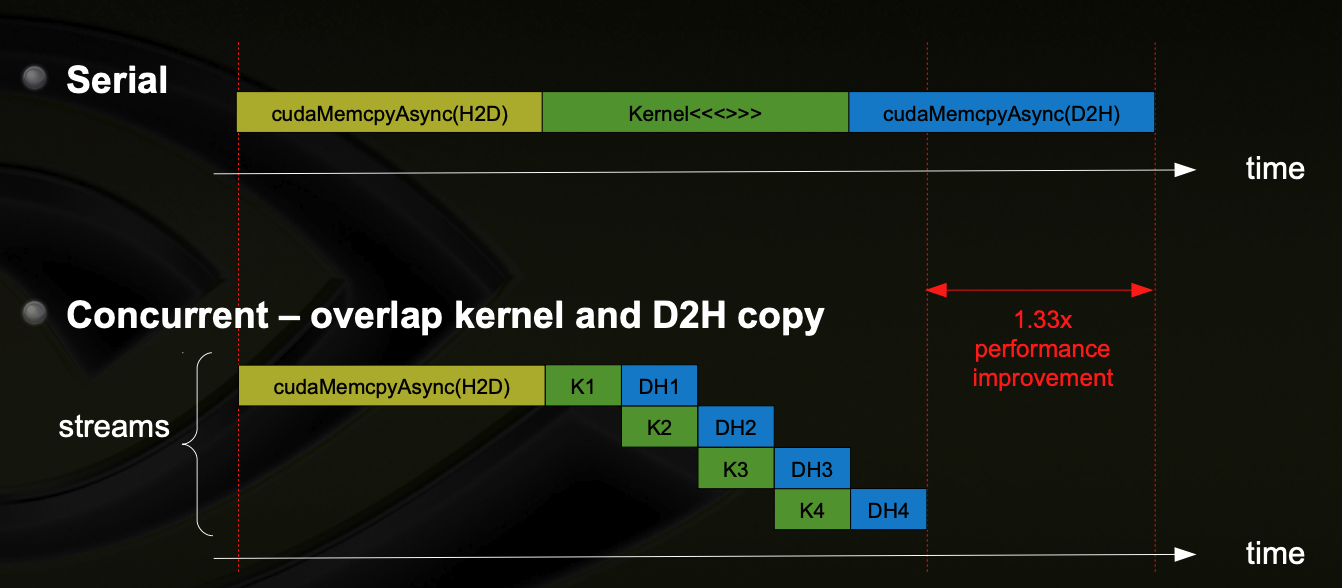
stream

A sequence of operations that execute in issue-order on the GPU

  • CUDA operations in different streams may run concurrently
  • CUDA operations from different streams may be interleaved
    cuda stream example

event

events are synchronization mechanisms used to measure and manage time, particularly for timing purposes and performance profiling.

  • event creation
    1
    2
    3
    4
    5
    #include <cuda_runtime.h>

    cudaEvent_t startEvent, stopEvent;
    cudaEventCreate(&startEvent);
    cudaEventCreate(&stopEvent);
  • record event
    1
    2
    3
    cudaEventRecord(startEvent, 0);
    // ... GPU code to be timed ...
    cudaEventRecord(stopEvent, 0);
    Here, cudaEventRecord records the current time in the events startEvent and stopEvent. The second argument, 0, specifies the stream in which to record the event (0 means the default stream).
  • synchonize events
    1
    cudaEventSynchronize(stopEvent);
    This function call makes the CPU wait until the GPU has completed all tasks associated with the stopEvent.
  • Calculate Elapsed Time
    1
    2
    float milliseconds = 0;
    cudaEventElapsedTime(&milliseconds, startEvent, stopEvent);
  • destroy event
    1
    2
    cudaEventDestroy(startEvent);
    cudaEventDestroy(stopEvent);

keywords

  • global functions that are executed on the GPU, called from CPU

  • device functions that are executed on the GPU, called within GPU

  • shared

  • align is a compiler directive that can be used to specify alignment requirements for variables in device code.

  • __launch_bounds__
    the launch_bounds attribute is used to specify launch bounds for a kernel function. The launch bounds control the number of threads per block and the maximum number of blocks per multiprocessor for a specific kernel.

    1
    __launch_bounds__(maxThreadsPerBlock, minBlocksPerMultiprocessor)

macros

  • CUDACC is a predefined macro in CUDA C/C++ that is used to determine whether the code is being compiled by the NVIDIA CUDA C/C++ compiler (nvcc).
  • NVCC is a predefined macro that is automatically defined by the NVIDIA CUDA compiler (nvcc). It allows you to conditionally compile code based on whether the code is being processed by the CUDA compiler or a regular C++ compiler

usage

the triple-chevron notation <<<...>>> is used to specify the execution configuration of a CUDA kernel launch.

1
kernel<<<gridDim, blockDim, sharedMem, stream>>>(...);
  • gridDim: Specifies the dimensions of the grid (number of blocks). It can be a 1D, 2D, or 3D configuration, specified as (gridDimX, gridDimY, gridDimZ).

  • blockDim: Specifies the dimensions of each block (number of threads per block). It can also be a 1D, 2D, or 3D configuration, specified as (blockDimX, blockDimY, blockDimZ).

  • sharedMem: Optional parameter specifying the dynamic shared memory per block in bytes. If not specified, it defaults to 0.

  • stream: Optional parameter specifying the CUDA stream in which the kernel should be executed. If not specified, it defaults to the default stream (0).

cuda standard api & tools

API

  • __syncthreads(): A thread’s execution can only proceed past a __syncthreads() after all threads in its block have executed the __syncthreads()
  • __syncwarp() is an intrinsic function that provides a warp-level synchronization point within a warp. A warp is a group of threads in CUDA that execute instructions in lockstep.

Tool

cmd

  • nvidia-smi

references

cryptography arithmetic tricks

  • get the next m*SIZE
    1
    2
    # define WARP_SZ 32
    size_t n = (nelems+WARP_SZ-1) & ((size_t)0-WARP_SZ)
    0-WARP_SIZE = 0xffffffffffffffe0
    eo = 0b11100000
    it will select multiples of WARP_SZ
    nelems+WARP_SZ-1 will counter for the removed numbers by 00000

n will be [32, 64, 96, …]

  • make a value to be 1<<N
    1
    2
    3
    uiint32_t a;
    while(a & (a-1)) // equal to 0 only when a is 1<<N
    a -= (a&(0-a)); // subtract the first 1 bit